LLM Royale, series 1, Haiku 4.5 vs GPT-5.4-mini
Game 2
Clash Royale, 1v1 ladder · Best of three · 5 August 2026
- Game 1
- Game 2
- Game 3
Figure 1. Boxes and labels are the harness's own detections; the header is the board summary the model was sent. Left, Claude Haiku 4.5 as yisu. Right, GPT-5.4-mini as Builder69.
Results
GPT-5.4-mini won the second game two crowns to nil, and the series 2–0, so there is no game three. The gap from game one widened: 181 decisions to Haiku's 126 across a match that ran into overtime, at a median of 0.81 s a call against 1.14 s. Haiku was the more selective of the two, placing 42 times in 126 decisions against 45 in 181, and still did not take a tower.
| Claude Haiku 4.5 | GPT-5.4-mini | |
|---|---|---|
| Crowns | 0 | 2 |
| Decisions | 126 | 181 |
| Cards placed | 42 | 45 |
| Decisions per minute | 32.7 | 46.8 |
| Median model call (s) | 1.14 | 0.81 |
| 95th percentile model call (s) | 2.94 | 1.78 |
| Slowest model call (s) | 9.62 | 6.45 |
| Loop blocked on the model (%) | 82 | 80 |
| Mean snapshot bytes the board summary, as sent | 1640 | 1609 |
| Prompt tokens per call mean | 1718 | 1231 |
| Prompt characters per token instructions plus snapshot | 2.24 | 3.10 |
| Match length (s) regulation plus overtime | 231 | 232 |
Table 1. Bold is the better of the two on that row. Model-call times are the API call alone; capture and the tap that follows it are not counted. Crowns are the count on the arena HUD at the final whistle. The recordings stop at Match Over, just before the result screen.
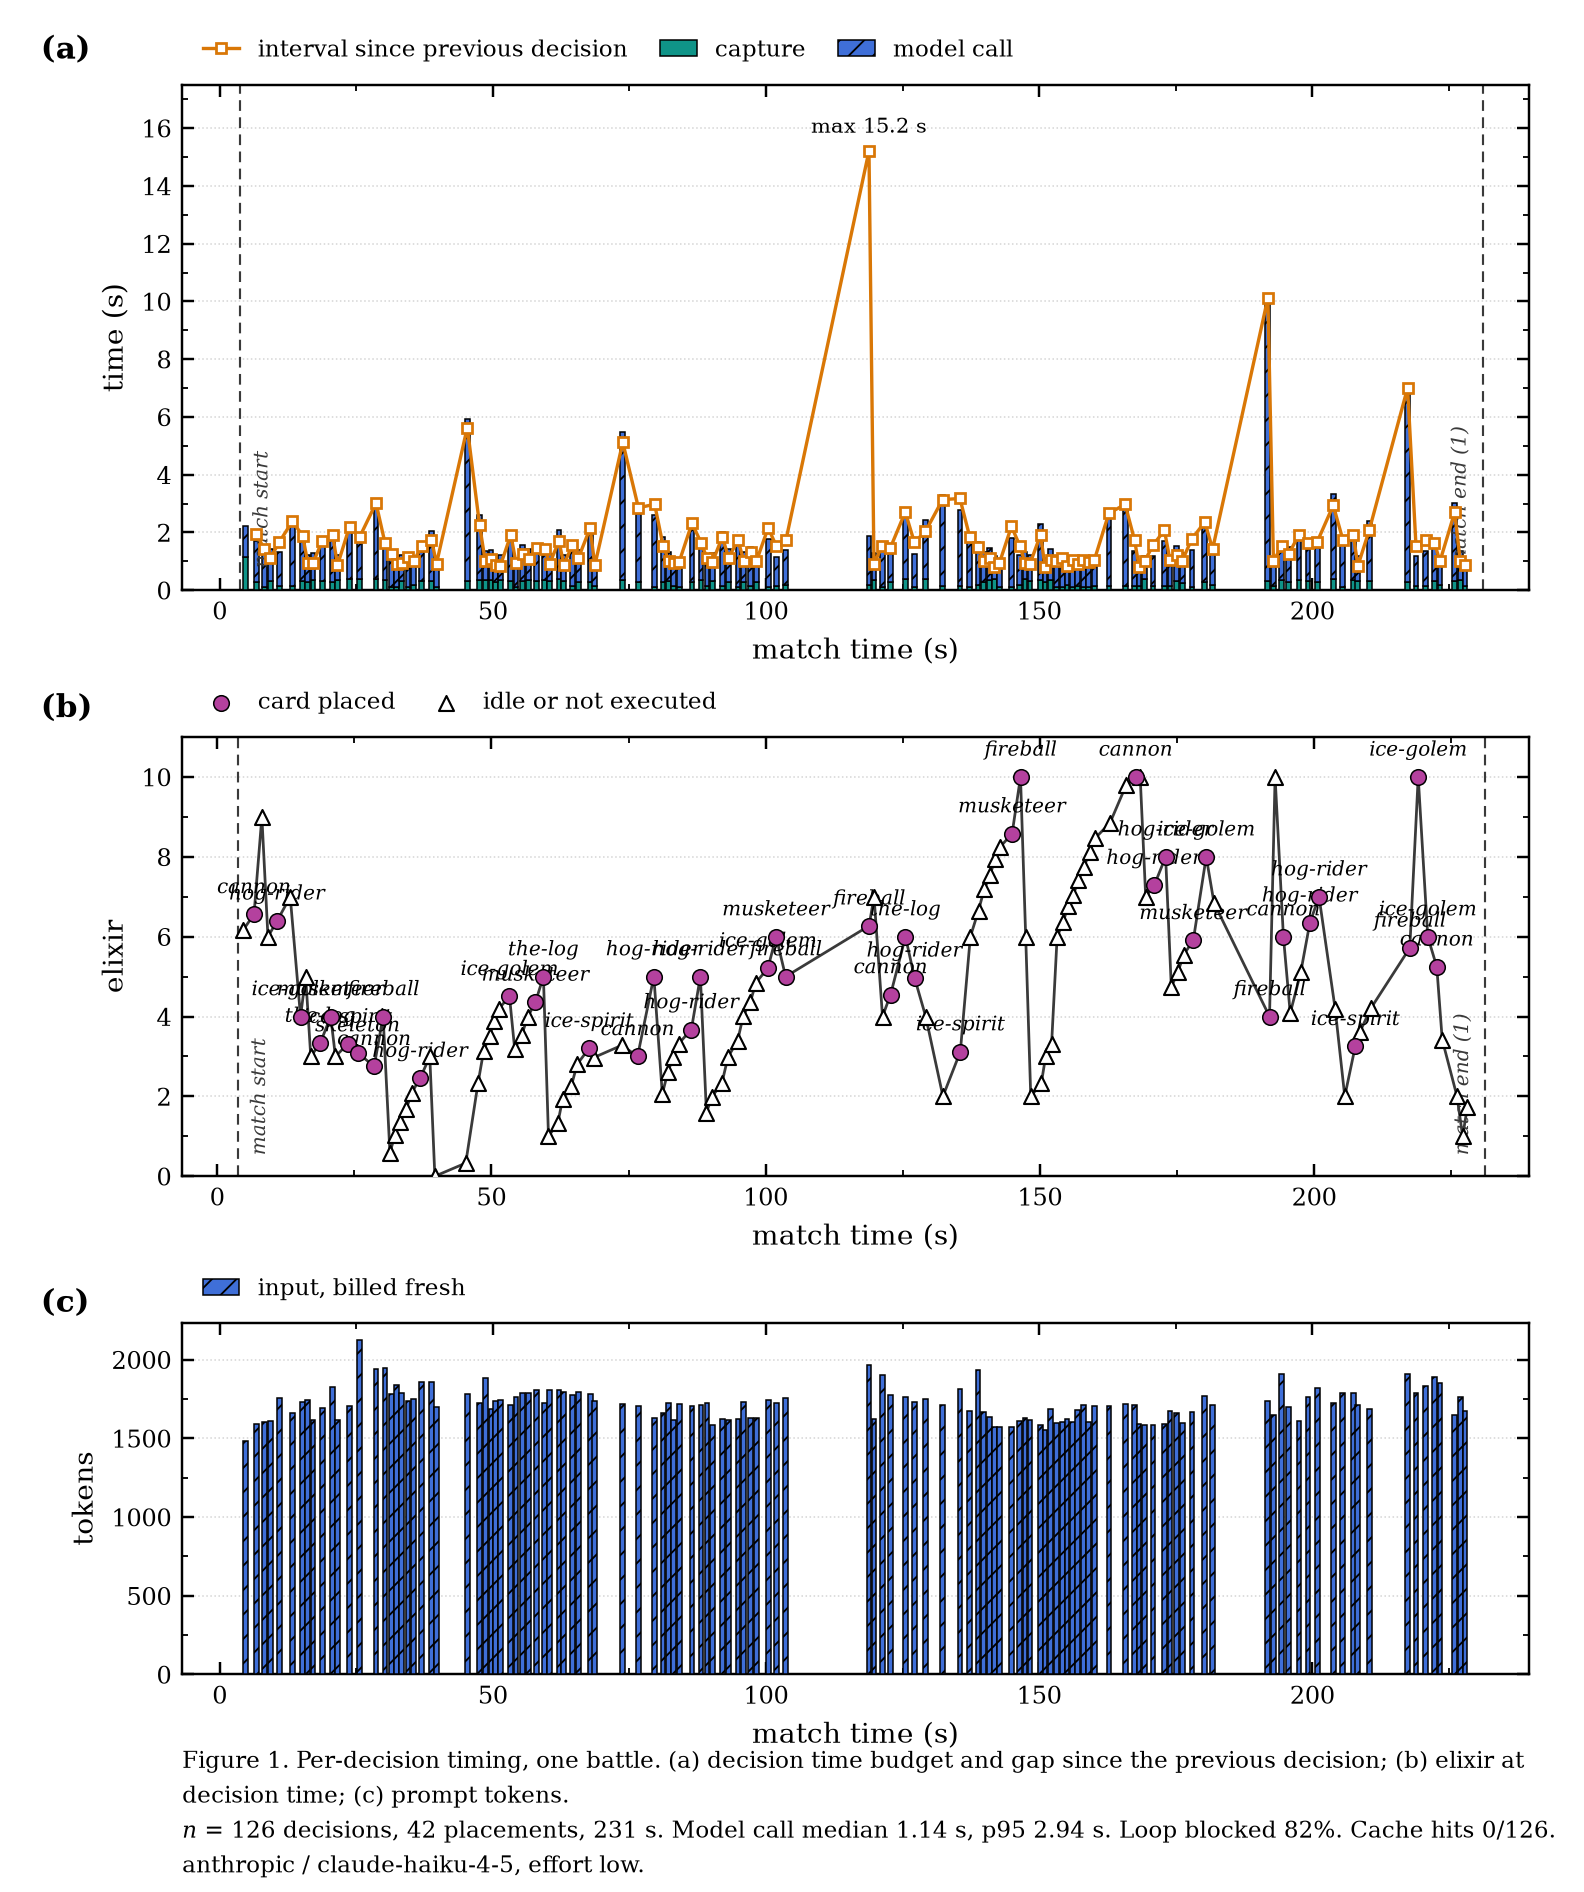
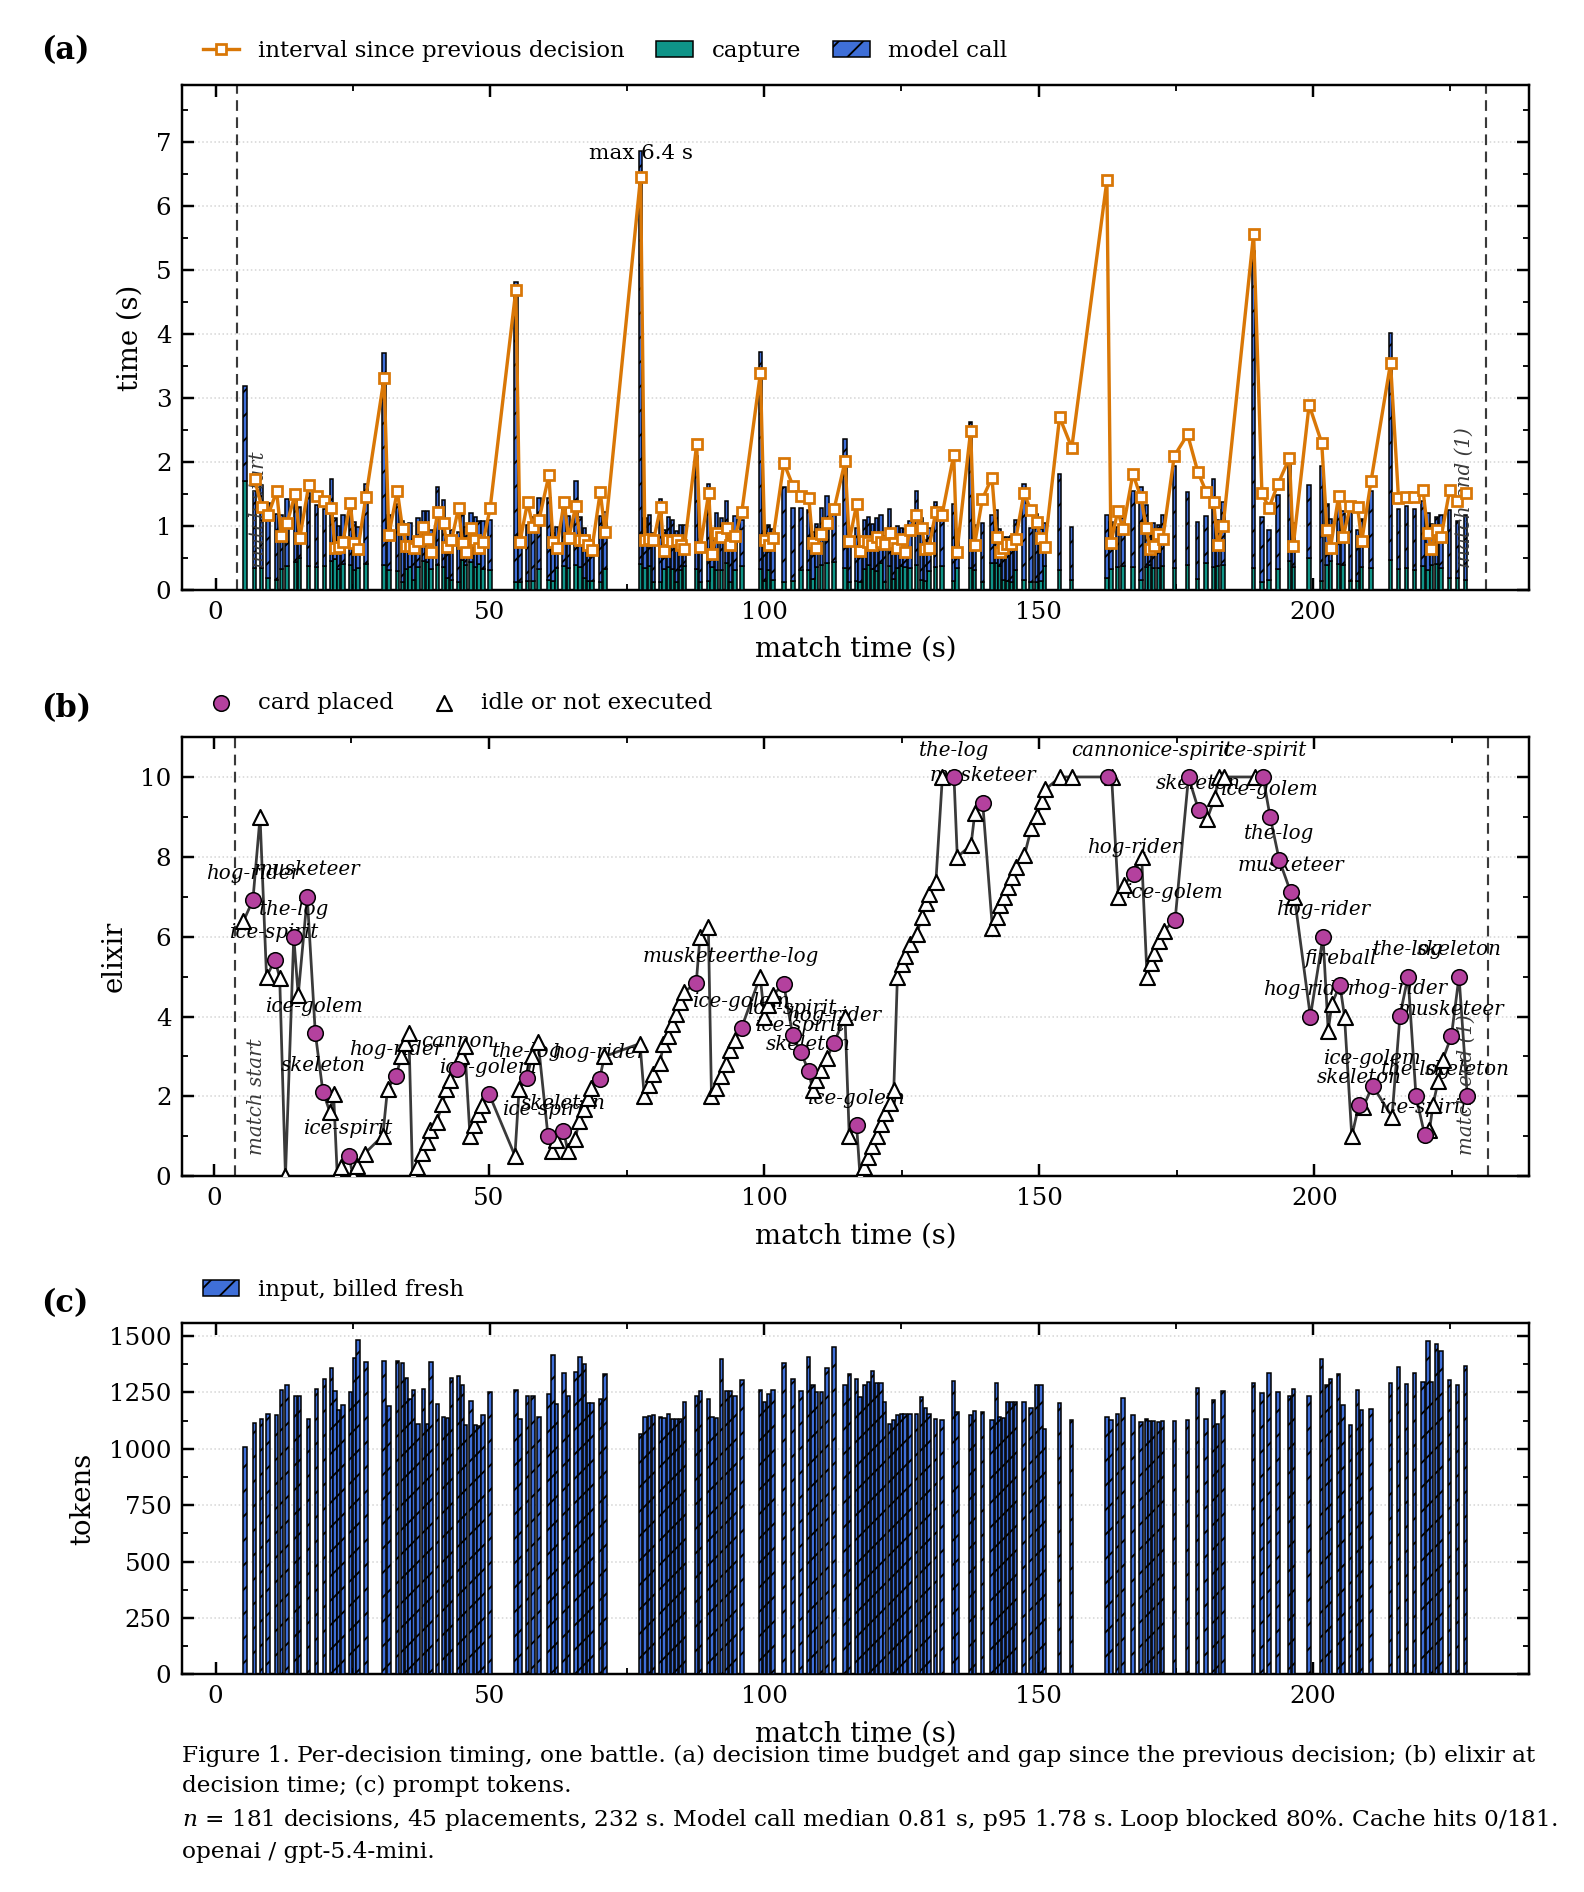
Figure 2. Per decision, from the log. (a) how long the decision took and how long since the previous one; (b) elixir at decision time, and the card played; (c) prompt tokens, none of them cached.